 @ (주)GS
2024Full-Stack
GS Inc. AI Agent Platform
Platform launch • workflow builder • AX training, self-service operations, fully realized.
View details
Took an environment where VOC piled up as dead data and built it into a unified analysis system from zero.
The mission was one line. Once I looked inside, classifier accuracy was actually the smallest problem — four channels (app, call, survey, social) were piling up in different places, junk like "hhhhhh" was flowing through to the classifier, and the CS team was reclassifying thousands of items every week by hand, paying for the missing system with people.
The job was not to build one good classifier. It was to stand up the full loop — ingest, clean, classify, act — from zero. That was where the project actually started.
Field notes
There was no unified ingest
The four channels — app, call, survey, social — were piling up in separate places.
There was no gate in front of the classifier
"hhhhhh", "lol"-equivalents, and empty strings flowed straight through into the 60 categories.
People were holding the system up
CS was reclassifying thousands of items every week by hand.
tradeoffKorean-topic accuracy vs. API cost
A "neutral classifier persona" system prompt blocked LLM hallucination. A gaslighting-style pattern broke any carryover from the previous turn.
Junk text was removed before it reached the LLM, using regex and length rules. Cut unnecessary API calls by 30% and recovered more accuracy on top.
Vector embeddings plus topic matching restructured the 60 categories into 6 intents × 10 sub-categories. Turned it into a searchable analytics asset.
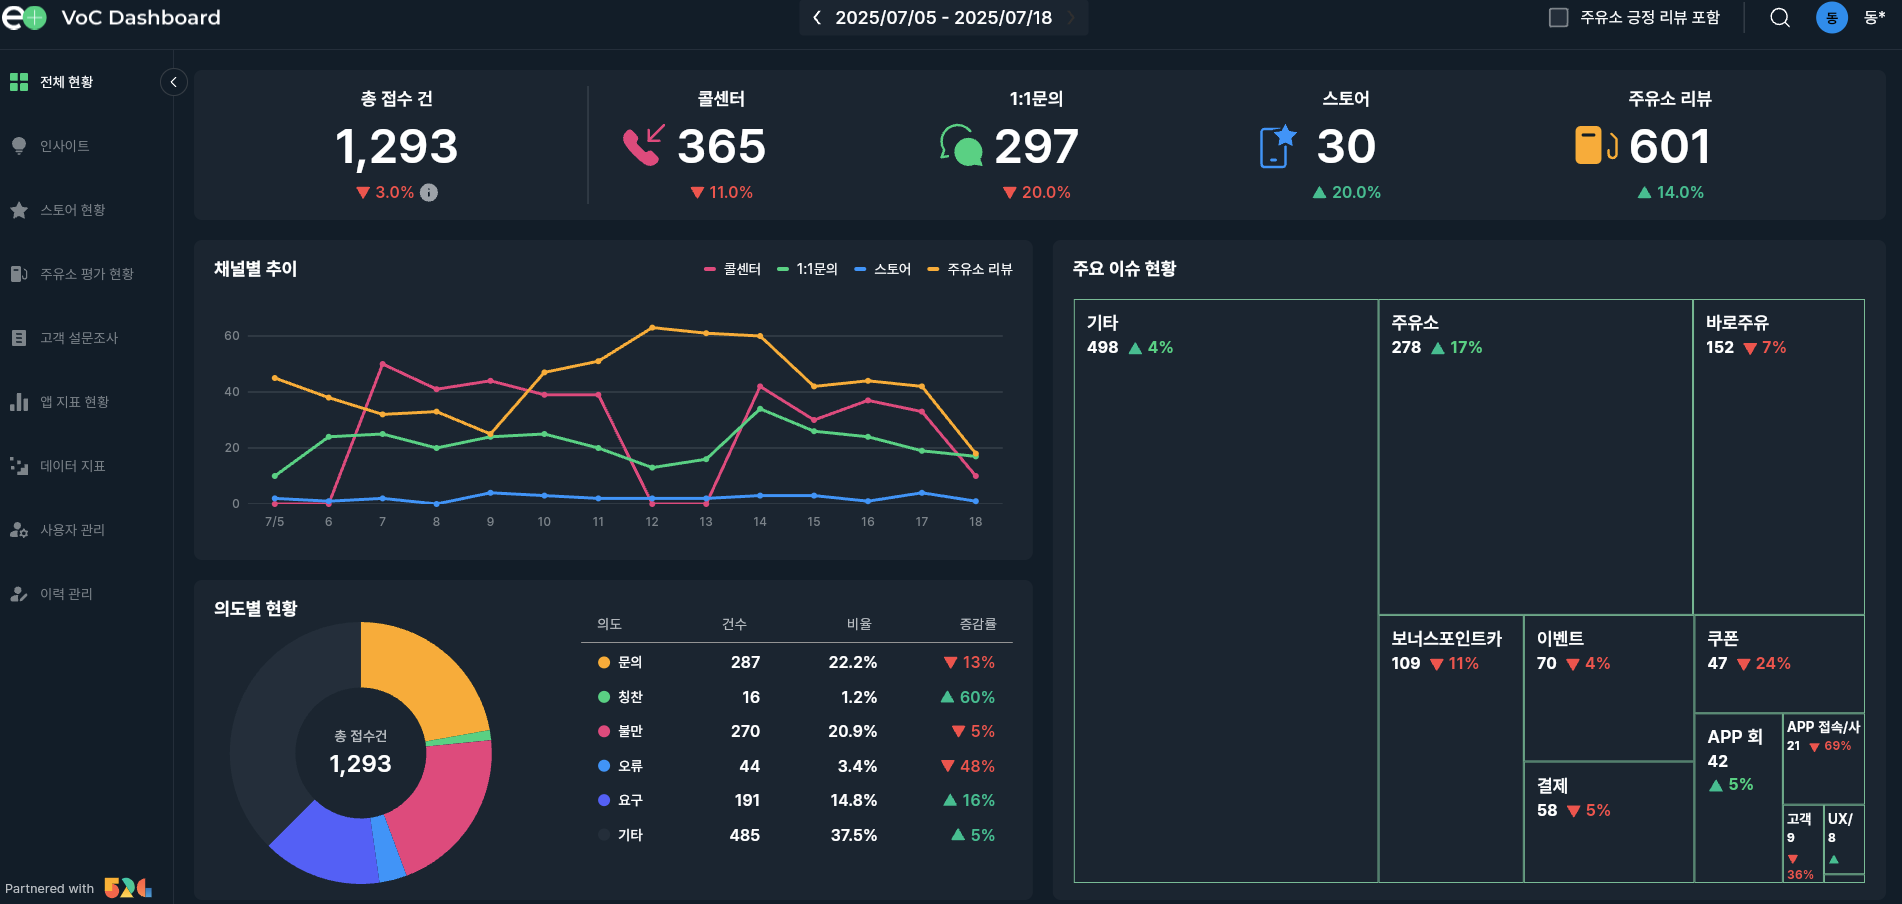
Manual → automated
0 → 1000+
CS classifications / day
Topic accuracy
70 → 88%
+18pp
Auto-ingest channels
4 channels
App · call · survey · social
API cost
−30%
Junk blocked by preprocessing rules
“An engineer who picks the metrics, owns the cost-vs-accuracy tradeoffs, and uses AI as a thinking tool.”
Read 60-category ambiguity as a pattern out of the live ops data.
Compared and swapped LLMs, tuned the prompts, lifted accuracy by 18 points.
CS hand-tagging went from zero to 1000+ classifications per day; API bill dropped 30%.
More work
@ (주)GSPlatform launch • workflow builder • AX training, self-service operations, fully realized.
 @ 외주 턴키
MVP shipped in 2 months (solo full-stack). Validated: 4.6 on Google Play, 1,000+ downloads.
 @ 스타트업
"You shouldn't have to know how to talk to an AI." The moment a user feels they're writing a prompt, the product has failed.